OpenAI has introduced Ultrafast, a new API service tier that runs GPT‑5.6 Sol at up to 14 times the speed of Standard processing. Powered by Cerebras, the limited-preview service can generate up to 750 output tokens per second, potentially bringing frontier-level AI to incident response, voice assistance, financial research, commerce, and other applications where every second matters.
OpenAI Introduces a New Speed Tier for GPT‑5.6 Sol
The competition among artificial intelligence companies is no longer defined by model intelligence alone. Response time, throughput, reliability, operating cost, and the ability to complete useful work during a live interaction have become equally important.
OpenAI is addressing the performance side of that equation with GPT‑5.6 Sol Ultrafast, a new service tier launching first through the OpenAI API.
According to OpenAI’s August 13, 2026 announcement, Ultrafast can run GPT‑5.6 Sol at up to 14 times the speed of the company’s Standard processing tier. The Cerebras-powered service can generate up to 750 output tokens per second.
The development is notable because applications have traditionally obtained faster responses by moving to smaller or more specialized models. Ultrafast is intended to provide substantially higher inference speed without requiring developers to give up the intelligence of OpenAI’s flagship GPT‑5.6 Sol model.
ITD Insight
Ultrafast is not a smaller GPT model or a new reasoning setting. It is a service tier designed to run GPT‑5.6 Sol on high-speed Cerebras infrastructure. OpenAI reports performance of up to 14× Standard processing and up to 750 output tokens per second, although actual application performance will depend on the workload.
What Is GPT‑5.6 Sol Ultrafast?
GPT‑5.6 Sol is OpenAI’s flagship model for complex professional work, including advanced reasoning, coding, research, document analysis, and tool-assisted workflows. The standard model supports capabilities such as streaming, function calling, structured outputs, image input, prompt caching, and configurable reasoning effort.
Ultrafast does not appear to change the underlying model or introduce a separate intelligence tier. Instead, it provides a faster way to run GPT‑5.6 Sol through OpenAI’s API platform.
The distinction matters. Developers choosing a smaller model can often improve latency and reduce costs, but they may also encounter lower performance on difficult tasks. Ultrafast is designed to make Sol’s higher level of intelligence available in workflows that previously could not tolerate the model’s standard response time.
OpenAI describes the offering as a new service tier rather than a universal upgrade to every GPT‑5.6 Sol request. Access is currently restricted to a limited group of customers participating in the preview.
Ultrafast Performance Claims
OpenAI has published two principal performance figures for the service:
- Up to 14× faster processing: OpenAI compares Ultrafast with its Standard processing tier.
- Up to 750 output tokens per second: This represents the maximum reported output-generation rate.
The phrase “up to” is important. OpenAI is presenting maximum performance figures, not promising that every request will be exactly 14 times faster or generate 750 tokens per second.
Observed performance may vary according to prompt length, output length, reasoning effort, tool use, request concurrency, network conditions, and the structure of the application. Time to first token and total workflow completion time may also differ from the raw output-generation rate.
OpenAI has not yet published general pricing for the Ultrafast tier or detailed benchmark results covering a broad range of workloads. Developers should therefore avoid using the maximum figures as guaranteed production estimates.
Powered by Cerebras
Ultrafast is powered by Cerebras as part of a partnership focused on bringing ultra-low-latency inference to OpenAI’s platform. Cerebras is known for developing wafer-scale AI processors designed to handle large models with high computational throughput.
The infrastructure partnership allows OpenAI to offer a distinct high-speed processing tier while keeping GPT‑5.6 Sol available through its API ecosystem. For developers, the most important result is the possibility of using a frontier model in interactive applications without switching to a less capable model solely to obtain faster output.
OpenAI has not disclosed every technical detail behind the deployment. Claims involving specific optimization methods, internal model changes, cache designs, or speculative decoding should not be presented as facts unless the companies provide additional documentation.
Where Ultrafast Could Make the Biggest Difference
OpenAI is initially evaluating the service in business environments where response delays can materially affect the user experience or operational outcome.
Incident Response and System Reliability
When a critical service fails, engineering teams must rapidly interpret application logs, infrastructure traces, recent code changes, monitoring alerts, and internal discussions.
OpenAI says its developers have used Ultrafast to help gather evidence, identify likely causes, determine the next diagnostic steps, and prepare or validate possible fixes. Human engineers remain responsible for judgment and deployment decisions, but faster analysis could shorten the time between detecting an incident and taking corrective action.
Financial Research and Security
Financial and security conditions can change faster than a lengthy AI workflow can complete. Higher-speed inference could help analysts review market signals, assess transactions, organize research, and identify potentially suspicious activity while the underlying conditions are still developing.
These applications still require appropriate human oversight, data controls, validation, and regulatory compliance. Faster output does not eliminate the possibility of inaccurate conclusions.
Customer Support and Voice AI
Voice assistants and live customer-service systems are particularly sensitive to latency. Even a capable model can produce a poor experience if users must wait through unnatural pauses while it searches for information or completes a multistep task.
OpenAI reports that early customers are exploring Ultrafast for complex support and voice workflows that may involve retrieving account information, consulting several systems, applying policies, and generating an answer during an active conversation.
Commerce
Online retailers could use faster AI to answer product questions, confirm inventory, personalize recommendations, and help resolve checkout issues while a customer is still considering a purchase.
In this setting, response time can directly affect whether the interaction continues or becomes an abandoned session. The value of Ultrafast will depend on whether its additional speed produces measurable improvements in engagement, conversion, or customer satisfaction.
Interactive Research and Experimentation
Some research workflows require users to submit a request, wait for a long batch process, review the result, and repeat the cycle later. OpenAI says Ultrafast could compress that loop enough to support several iterations during a working session.
More responsive research systems could let users test an idea, examine the results, revise the approach, and begin another experiment without breaking their flow.
What Early Customers Are Testing
OpenAI is testing GPT‑5.6 Sol Ultrafast with an initial group of organizations working across coding, commerce, financial research, customer support, and other interactive applications.
The preview is intended to help OpenAI determine where an order-of-magnitude increase in output speed creates meaningful business value. Early participants cited in the announcement include Jane Street, Podium, Basis, and Rogo.
Their reported experiences suggest that higher inference speed can change more than how quickly text appears on a screen. It may allow developers to design synchronous applications around complex model capabilities that previously worked better as asynchronous or background processes.
These accounts should still be understood as early customer experiences rather than independent benchmarks. Broader testing will be necessary to determine how the service performs across different prompts, industries, application designs, and traffic levels.
Ultrafast Availability
GPT‑5.6 Sol Ultrafast is currently available only as a limited preview for selected OpenAI API customers. OpenAI says it will expand availability as capacity increases, but the company has not announced a date for general access.
Organizations interested in the service can use the access-updates form linked from OpenAI’s announcement. Signing up does not necessarily provide immediate access.
OpenAI has also not announced:
- General API pricing for Ultrafast processing
- Guaranteed service-level performance
- Regional availability
- Default rate limits
- A general-release date
- Whether the tier will become available directly in ChatGPT
Until those details are published, cost and deployment planning will remain preliminary.
Ultrafast vs. Other GPT‑5.6 Performance Options
Ultrafast is not the only way developers can improve application responsiveness. OpenAI’s GPT‑5.6 family also lets developers select different models and adjust how much reasoning is used for a request.
- GPT‑5.6 Sol: The flagship option for difficult professional, reasoning, research, and coding workloads.
- GPT‑5.6 Terra: A balanced model for applications that need strong capabilities at a lower operating cost.
- GPT‑5.6 Luna: An economical model for efficient, high-volume, and cost-sensitive tasks.
For routine classification, extraction, routing, or summarization, Terra or Luna may remain more economical than running Sol through a premium high-speed tier. Ultrafast is most compelling when an application needs both Sol-level intelligence and very low latency.
Other Ways to Reduce GPT‑5.6 Latency
Developers without access to the Ultrafast preview can still improve GPT‑5.6 application performance through established optimization techniques.
Select the Appropriate Model
The smallest model that consistently meets the quality requirement is often the best production choice. Teams should compare Sol, Terra, and Luna using the same representative evaluation set.
Control Reasoning Effort
Lower reasoning settings can improve responsiveness on straightforward requests. Higher reasoning effort may help with difficult analysis, coding, planning, or multistep tasks but can require additional time and tokens.
Stream the Response
Streaming lets an application display output as it is generated rather than waiting for the complete response. This may not reduce total processing time, but it can significantly improve perceived responsiveness.
Use Prompt Caching
Applications that repeatedly send the same system instructions, tool definitions, examples, or reference material may benefit from prompt caching. Reusable content should be placed near the beginning of the prompt, with frequently changing information placed later.
Limit Unnecessary Context
Submitting irrelevant documents or excessive conversation history can increase processing requirements and make it harder for the model to identify the most important information. Retrieval systems should select only the context required for the current task.
How Developers Should Evaluate Ultrafast
Raw output speed is only one part of application performance. When access becomes available, organizations should test Ultrafast with representative production workflows and measure:
- Time to first token: How long the user waits before output begins.
- Output rate: How quickly the response is generated after it starts.
- End-to-end latency: The total time required to complete the request or workflow.
- Tail latency: Performance for slower requests at the 95th or 99th percentile.
- Task quality: Whether the result satisfies the application’s accuracy requirements.
- Tool latency: Time spent waiting for searches, databases, functions, and external services.
- Cost per successful task: The total expense of obtaining an acceptable result.
A model that generates text at 750 tokens per second can still be delayed by slow external tools, oversized prompts, network conditions, or sequential application logic. Developers should benchmark the complete workflow instead of treating tokens per second as the only meaningful measurement.
Why the Announcement Matters
Ultrafast represents an effort to reduce the traditional compromise between intelligence and speed. Until now, developers building real-time applications often selected smaller models because flagship systems could not respond quickly enough for voice, coding, support, and other synchronous experiences.
If OpenAI can deliver GPT‑5.6 Sol’s capabilities at the advertised speed across practical workloads, developers may be able to use frontier reasoning in applications that previously required simpler models or lengthy background processing.
The commercial importance will depend on several unanswered questions, particularly pricing, availability, rate limits, consistency, and performance under production traffic. A service can be technically impressive but still be unsuitable for a workload if its cost exceeds the value created by the reduced latency.
The Bottom Line
GPT‑5.6 Sol Ultrafast is an officially announced OpenAI service tier powered by Cerebras. OpenAI says it can run Sol at up to 14 times the speed of Standard processing and generate as many as 750 output tokens per second.
The service could make frontier-level AI practical for incident response, voice assistance, customer support, financial research, commerce, coding, and interactive experimentation. It also suggests that AI infrastructure competition is expanding beyond model quality into the amount of useful work a system can complete per second.
Ultrafast remains a limited preview, however. OpenAI has not announced general pricing, guaranteed performance, or a broad release date. The reported figures should therefore be treated as maximum claims until customers can test the service across a wider range of production workloads.
For organizations that require both GPT‑5.6 Sol’s intelligence and extremely low latency, Ultrafast could become an important new deployment option. For less demanding or cost-sensitive applications, Terra, Luna, lower reasoning settings, streaming, prompt caching, and careful context management may remain the more practical choices.
 |
Google Cuts Gemini 3.7 Flash Pricing for Coding AgentsSee how Google’s Gemini 3.7 Flash price reduction could lower the cost of coding agents, high-volume automation, and other latency-sensitive AI workloads. |
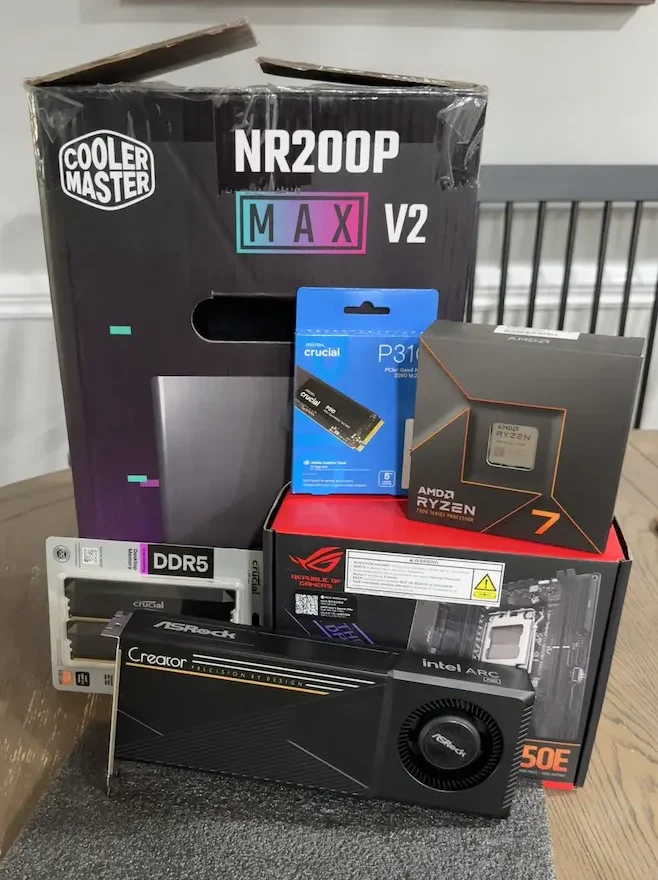 |
I Built a Prime Day Mini AI PC Around an Open-Box 24GB Intel Arc Pro B60See how a compact AM5 system with 24GB of GPU memory brings serious local AI experimentation within reach of home users, creators, and homelab builders. |